Prototype models, test feature pipelines and build demos with labelled datasets whose features are correlated the way real ones are, and contain no real person.
Free trial for every new account. No credit card.
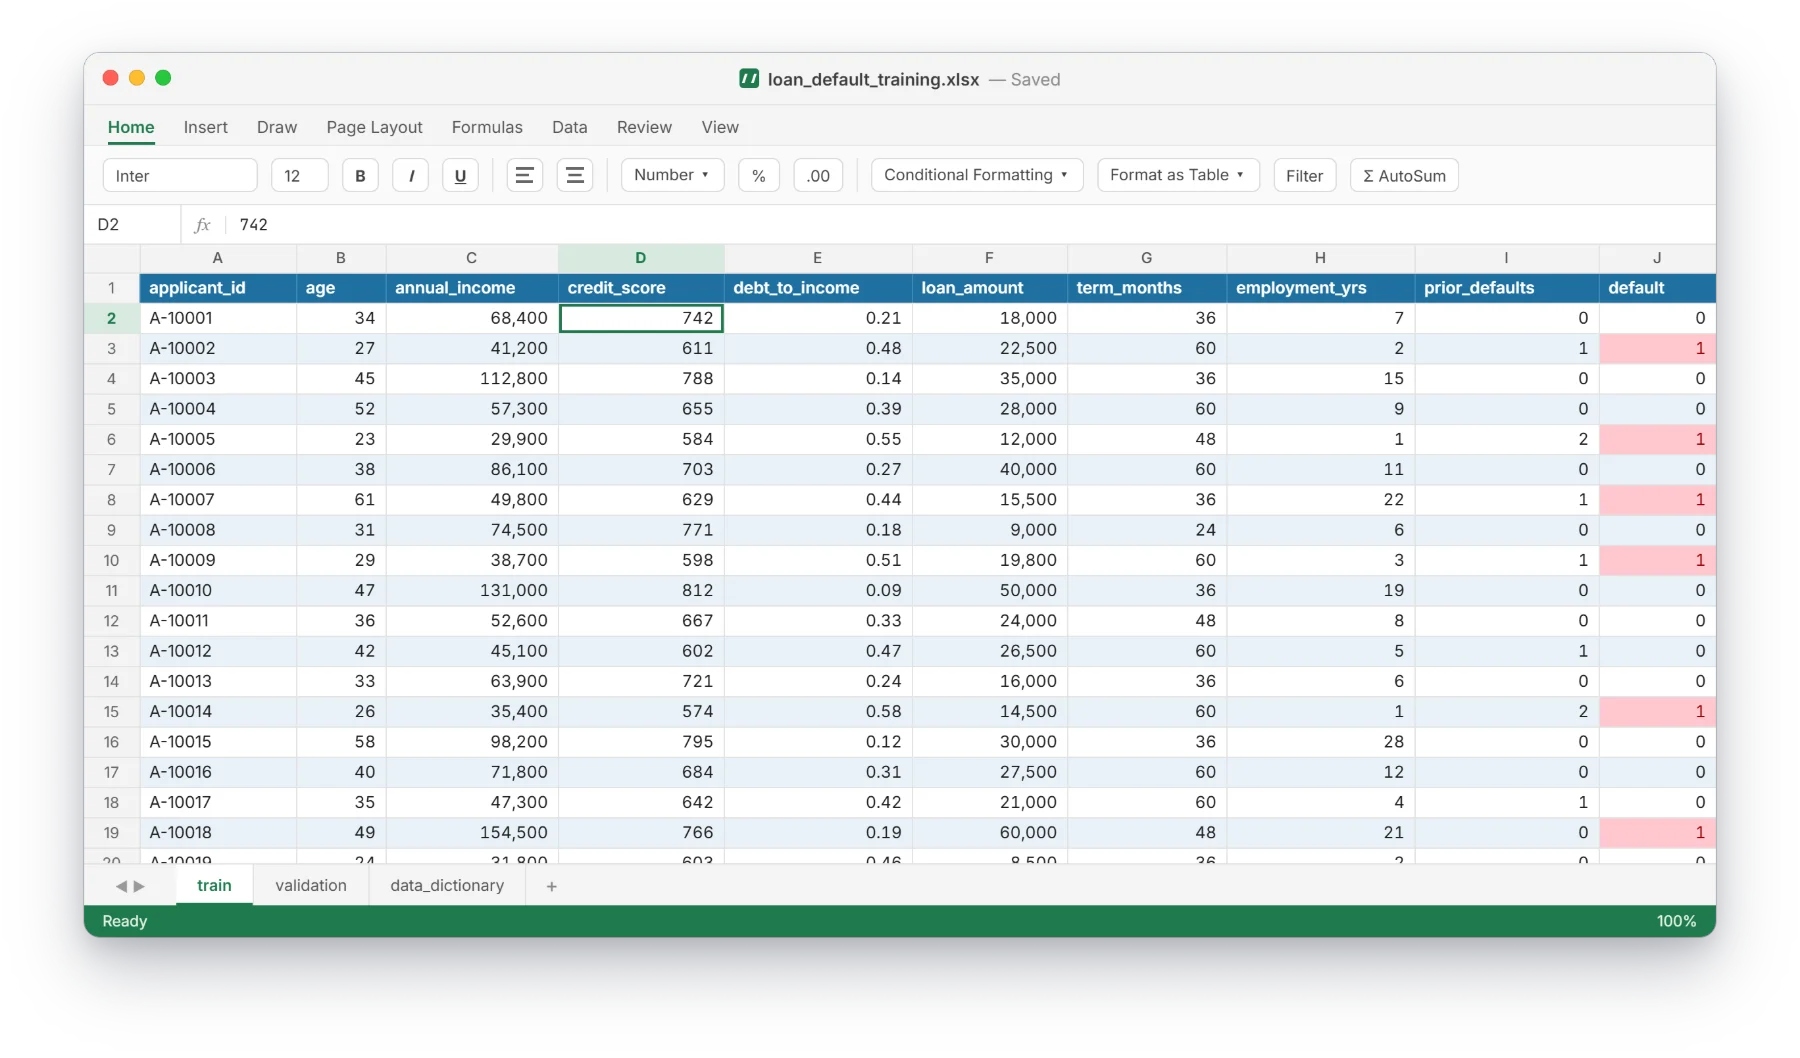
What to look for in the screenshot above. These are the details that usually break in hand-made or random test data.
Set how columns relate (for example, credit score vs. default) and the data follows it.
Gaussian, skewed, power-law and categorical mixes instead of uniform noise.
Make the positive class rare or common to test imbalance handling.
Every row is synthetic, so you can share datasets with vendors and in public demos.
Describe your data in plain English, or upload your SQL schema for PostgreSQL, MySQL / MariaDB, SQL Server and SQLite.
Check the tables, columns and rules the AI proposes, and adjust anything you like.
Choose how many rows you need and download a ready-to-run SQL script, CSV, Excel (one sheet per table) or JSON.
Use it to prototype, test pipelines and demo. It is designed to look realistic, not to copy the statistics of a specific real population.
Yes. Correlated columns take a target correlation (for example −0.4) and the data is generated to match it.
CSV, Excel, JSON or SQL. CSV loads straight into pandas.
Describe your tables or upload your schema. The free trial needs no credit card.
Start free